
Decoding the technologies of tomorrow, today.
Exploring the breakthrough innovations shaping our world. From AI infrastructure and robotics to biotech, quantum computing, and spatial tech.
Exploring the breakthrough innovations shaping our world. From AI infrastructure and robotics to biotech, quantum computing, and spatial tech.
AI systems can produce a polished, convincing answer in seconds, yet that answer may contain a wrong date, an invented citation, a distorted explanation, or a claim that has no reliable basis. These failures are commonly called AI hallucinations. The National Institute of Standards and Technology (NIST) uses the term confabulation for cases in which generative AI systems produce and confidently present erroneous or false content.
The problem is not simply that an AI system has “bad information stored inside it.” Incorrect outputs can arise from how language models are trained, limitations in their data, ambiguity in a user's request, and the way AI applications are designed around the model.
Understanding those causes makes it easier to decide when an AI response can be accepted, when it should be verified, and when the system needs additional safeguards.
A large language model is trained to learn statistical patterns from large collections of data. During pretraining, one central task is predicting the next token based on the tokens that came before it. NIST explains that this statistical prediction can produce factually accurate and consistent outputs, but it can also result in information that is factually inaccurate or internally inconsistent.
That distinction is easy to overlook because fluent language and factual accuracy often appear together in human writing.
Consider a user asking an AI system about an obscure historical event. If the model has encountered enough relevant information, it may produce a useful answer. But if the available patterns are incomplete or ambiguous, the model can still construct a response that resembles a legitimate historical explanation.
The resulting text may have the right names, sentence structure, and terminology while containing an incorrect detail.
The model is therefore not performing a simple database lookup every time it generates a response. Its ability to produce natural language does not guarantee that every factual statement has been independently verified.
One reason fabricated information is so troublesome is that the error often looks reasonable. A completely nonsensical response is easy to identify. A fabricated citation with a realistic-looking title, case name, quotation, and publication details can be much harder to recognize without checking the underlying source.
A well-known example occurred in 2023 in Mata v. Avianca, Inc. in the U.S. District Court for the Southern District of New York. Attorneys representing the plaintiff submitted a legal filing containing nonexistent judicial opinions and fabricated quotations and citations generated by ChatGPT. The court later determined that the cited cases did not exist and imposed a $5,000 monetary penalty on the attorneys and their law firm.
The incident is useful because the fabricated material was not obviously nonsensical. The citations, case names, and legal language looked sufficiently plausible to appear in a professional filing. The court's opinion emphasized that attorneys have a responsibility to verify the authorities they submit, regardless of whether an AI tool was involved.
The case illustrates a central problem with AI-generated information: plausibility is not proof.
The quality and coverage of training data also matter.
Large training datasets contain valuable information, but they can include errors, conflicting claims, outdated material, and incomplete coverage of less common subjects. NIST notes that confabulation is a natural consequence of the statistical generation process used by generative models, particularly in open-ended and long-form tasks.
Rare facts present a particular challenge. A model may have extensive exposure to information about a famous historical figure but comparatively little reliable material about an obscure person. When the available patterns are weak, the model may have difficulty determining which details are well supported.
This helps explain why AI can perform impressively on common subjects while producing surprisingly specific mistakes on obscure ones.
Training data also cannot automatically provide information that did not exist when the model was trained. For current events, changing regulations, recent product specifications, newly published research, or other time-sensitive subjects, an application may need access to current external sources rather than relying solely on information learned during training.
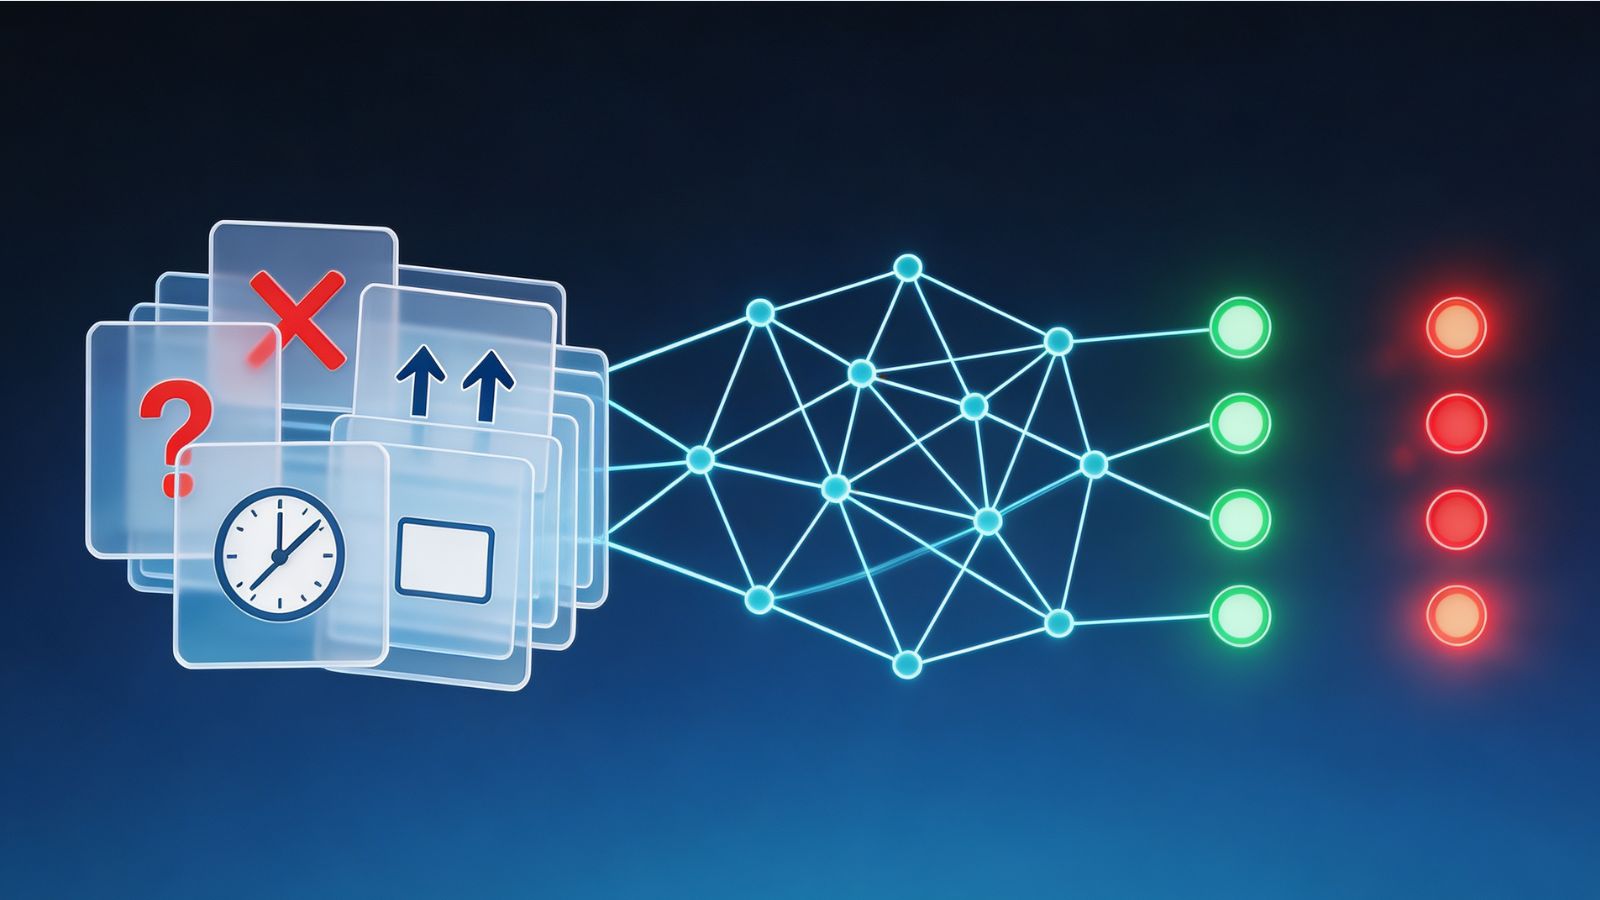
Not every incorrect AI answer results from missing knowledge.
Sometimes the user's question itself allows multiple interpretations.
A request such as “What is the largest company?” could refer to market capitalization, annual revenue, number of employees, or another measurement. If the user does not specify the intended definition, an AI system may select one interpretation and provide an answer without making that assumption clear.
The same problem occurs with incomplete instructions. A user may assume the system understands background information that was never provided.
A human expert might stop and ask a clarifying question. A generative AI system may instead attempt to be helpful by producing an answer based on its best interpretation.
That behavior can be convenient in ordinary conversation, but it creates risk when the distinction between assumptions and verified information matters.
AI-generated errors can also build on one another.
Suppose a system makes a small factual mistake near the beginning of a long explanation. Later statements may depend on that incorrect premise. The final response can therefore contain several related errors even though the original problem was a single mistaken assumption.
NIST specifically identifies outputs that contradict previously generated statements within the same context as a form of confabulation.
Complex multi-step tasks create additional opportunities for failure. An AI application may need to interpret a request, retrieve information, reason about it, summarize the result, and produce a final response. Each stage introduces another place where information can be misunderstood or transformed incorrectly.
This is one reason an AI system should be evaluated as a complete workflow rather than judged only by the underlying model.
Human readers naturally use confidence and fluency as signals of competence.
AI systems can unintentionally create the same impression because grammatical, well-structured language does not necessarily indicate factual certainty.
This distinction is especially important when a model has limited information. Instead of stopping at the boundary of what it can reliably establish, a generative system may produce the most plausible continuation of the conversation.
OpenAI's research on hallucinations has highlighted another complication: some evaluation methods reward models for producing correct answers but do not adequately reward appropriate uncertainty. Under those conditions, guessing can sometimes be more advantageous than acknowledging that the answer is unknown.
This does not mean an AI system is deliberately trying to deceive the user. The mechanism is fundamentally different from human intent. The system generates an output according to learned patterns, instructions, and the information available to it.
For users, however, the practical lesson is straightforward: confidence in the wording should not be treated as evidence that the underlying claim is true.
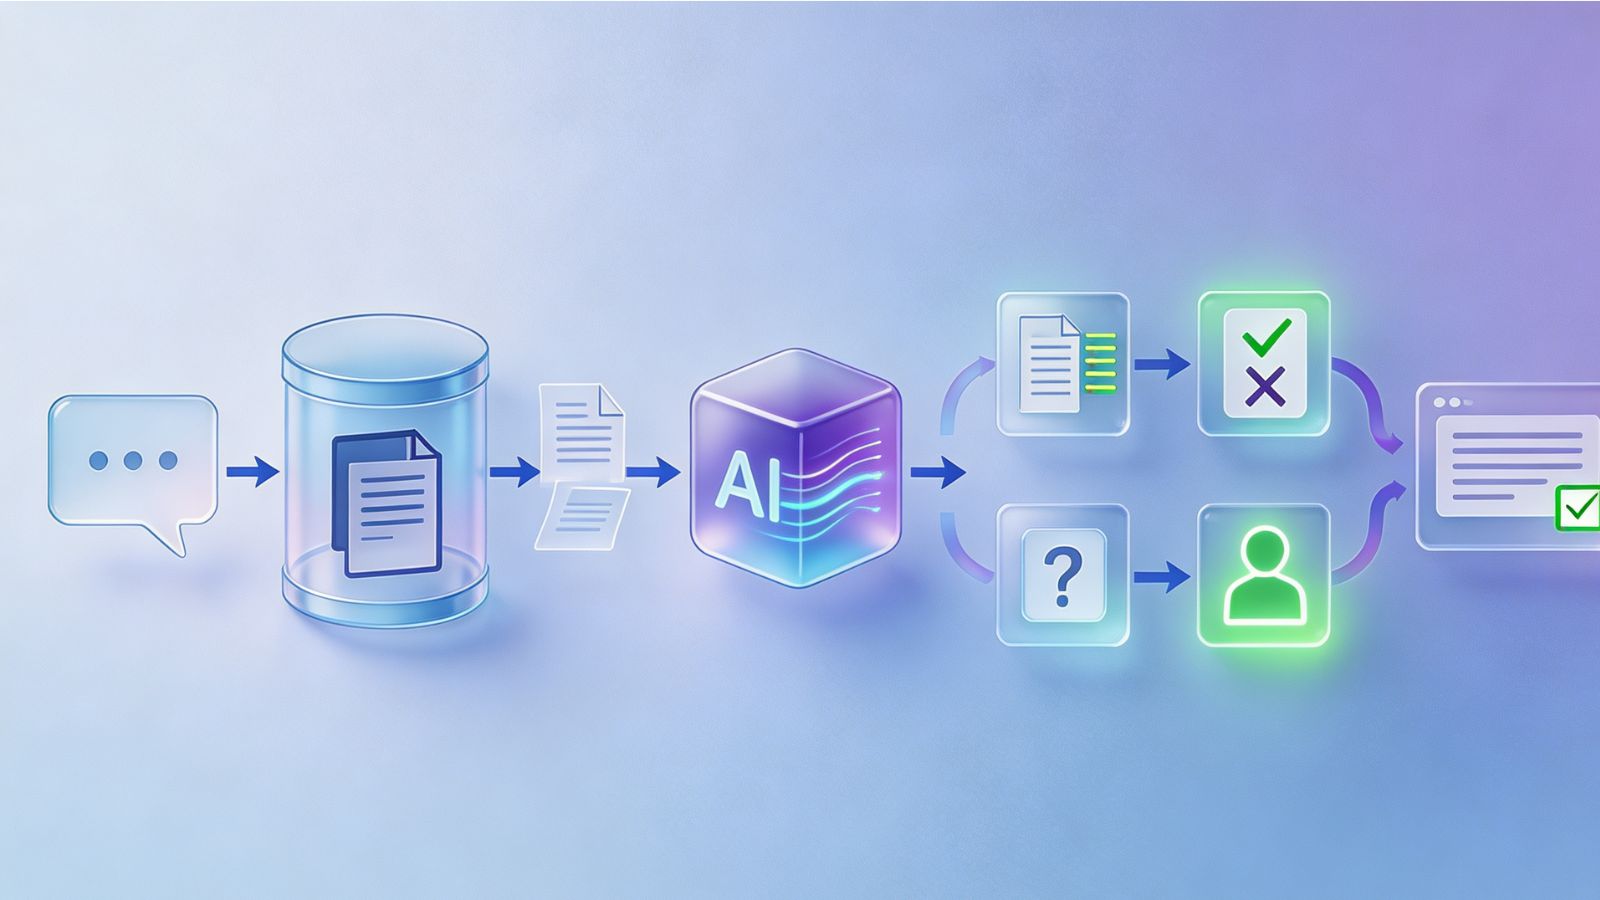
One way to reduce factual errors is to give an AI system access to reliable external information when it generates an answer.
This approach is commonly associated with retrieval-augmented generation (RAG). Rather than requiring the model to rely entirely on information encoded during training, an application can retrieve relevant documents or data and provide them as additional context.
Grounding can be particularly useful when information changes frequently or when an organization needs answers based on a specific collection of approved material.
But retrieval is not a guarantee of accuracy. The system can retrieve the wrong document, the source itself can contain an error, or the model can misunderstand the retrieved material.
External information therefore changes the failure mode rather than eliminating it. A reliable implementation still needs appropriate source selection, retrieval testing, and output evaluation.
For ordinary brainstorming or creative writing, a minor factual mistake may have little consequence. The standard should be much higher when an AI system is used for medical, legal, financial, scientific, or other consequential information.
NIST identifies confabulation as a risk because people may act on false information, particularly when generated content is used in consequential settings.
Practical verification can include checking important claims against authoritative sources, following citations back to their original documents, confirming dates and numbers independently, and asking the system to distinguish established information from assumptions.
For organizations, additional safeguards can include retrieval from approved sources, structured evaluation datasets, monitoring, human review, and testing for known failure modes.
The Mata v. Avianca case demonstrates why citation verification deserves particular attention. A citation that looks authentic is still only a claim until the underlying case, document, or publication can be independently located and confirmed.
AI systems produce incorrect or fabricated information because generating convincing language and establishing truth are different problems.
Training helps models learn remarkably complex patterns, but those patterns can be incomplete, ambiguous, outdated, or statistically misleading. Models can also encounter unclear questions and situations where the available evidence is insufficient. When the system generates a plausible continuation instead of recognizing uncertainty, the result can be a confident factual error.
That does not make AI useless. It means AI should be treated according to the requirements of the task.
For low-risk creative work, occasional inaccuracies may be manageable. For factual applications, important claims should be verified. For high-consequence decisions, AI output should not be treated as an unquestioned authority.
The most reliable approach is to combine capable models with appropriate sources, evaluation, uncertainty handling, and human judgment. The goal is not to assume that AI will never make a mistake. It is to build workflows in which mistakes are easier to detect before they matter.