
Decoding the technologies of tomorrow, today.
Exploring the breakthrough innovations shaping our world. From AI infrastructure and robotics to biotech, quantum computing, and spatial tech.
Exploring the breakthrough innovations shaping our world. From AI infrastructure and robotics to biotech, quantum computing, and spatial tech.
An AI system can produce an impressive answer and still be unsuitable for serious use. A response may sound authoritative while containing an incorrect fact, follow a different format from one request to the next, or fail unexpectedly when the input changes slightly.
That is why evaluating AI requires more than asking, “Does it usually give good answers?”
A useful evaluation separates at least three questions. Accuracy asks whether the output is correct. Consistency asks whether the system behaves predictably across comparable situations. Reliability asks whether the complete system continues to perform as intended under its expected conditions and over time.
The National Institute of Standards and Technology (NIST) treats validity and reliability as important characteristics of trustworthy AI and emphasizes that evaluation should be connected to the system's intended use rather than considered in isolation.
The first mistake in AI evaluation is testing a system against questions that do not represent its actual job.
A customer-service assistant, document summarizer, fraud-detection model, and research assistant have very different requirements. A benchmark score may provide useful information about a model's capabilities, but it cannot by itself establish that a deployed application is reliable for a particular purpose.
NIST recommends considering trustworthiness throughout design, development, deployment, use, and testing rather than treating evaluation as a single final step.
Before testing, define what a successful result means.
For a question-answering system, success might require an answer to be factually correct and supported by an approved source. For a classification system, the important measures may include false positives and false negatives. For a document-generation system, completeness, factual accuracy, and citation quality may matter more than whether the writing sounds natural.
The evaluation criteria should therefore come from the application's real requirements.
Evaluation should be tied to the system's intended use rather than judged in isolation. A reliable AI system is one that can be measured continuously, not just tested once.
Accuracy is fundamentally about whether the system's result is close to the correct or accepted result.
For AI applications, that sounds straightforward until the output is open-ended text.
Consider an AI assistant answering questions about a company's product documentation. A useful evaluation set should contain questions for which reviewers can establish the correct answer from authoritative material. The evaluator can then check whether the response contains the necessary facts, introduces unsupported claims, or leaves out information that changes the meaning.
For generated reports, evaluation can examine whether required information appears in an output and whether claims can be connected to source material.
This illustrates an important principle: accuracy should be measured against explicit criteria rather than general impressions of quality.
Human review can still be valuable, particularly for nuanced language, but reviewers should use defined standards. Otherwise, two evaluators may reach very different conclusions about what constitutes a good answer.
A system that performs well on ordinary examples may still fail badly on unusual inputs.
Evaluation should include representative cases as well as difficult cases. These might include ambiguous questions, incomplete information, unusually long inputs, misspellings, conflicting instructions, unfamiliar terminology, or requests that fall near the boundaries of the system's intended use.
This is where robustness becomes relevant.
NIST describes robustness and generalizability in terms of maintaining appropriate performance across different circumstances.
For example, suppose an AI system correctly identifies customer requests when they are written in a standard format. Testing only those examples may hide a problem. Real users may provide the same information in different wording, omit details, or combine several requests into one message.
A stronger evaluation deliberately varies the inputs while preserving the underlying task.
If a small change in wording causes a major change in performance, the system may require additional safeguards even if its average benchmark score looks strong.
Accuracy and consistency are related, but they are not identical.
A system can be accurate on average while behaving unpredictably on repeated or closely related requests. This matters when users expect stable outputs.
For example, an AI application might be asked to classify the same document several times. If the classification changes without a meaningful change in the input or system configuration, developers should investigate why.
Generative AI makes this issue particularly important because outputs can vary. Variability is not automatically a defect; some applications benefit from creative variation. But where the task requires a predictable result, the acceptable amount of variation should be defined before deployment.
Useful consistency tests include:
Repeated-input testing: Run the same request multiple times and examine meaningful differences.
Equivalent-input testing: Express the same requirement in different ways and compare outcomes.
Format testing: Determine whether required structures, fields, or constraints are followed consistently.
Boundary testing: Test inputs just inside and outside the application's intended operating range.
Regression testing: Re-run an established evaluation set after changing the model, prompt, retrieval system, or other components.
The goal is not necessarily identical wording every time. The real question is whether differences in output remain within an acceptable range for the application.
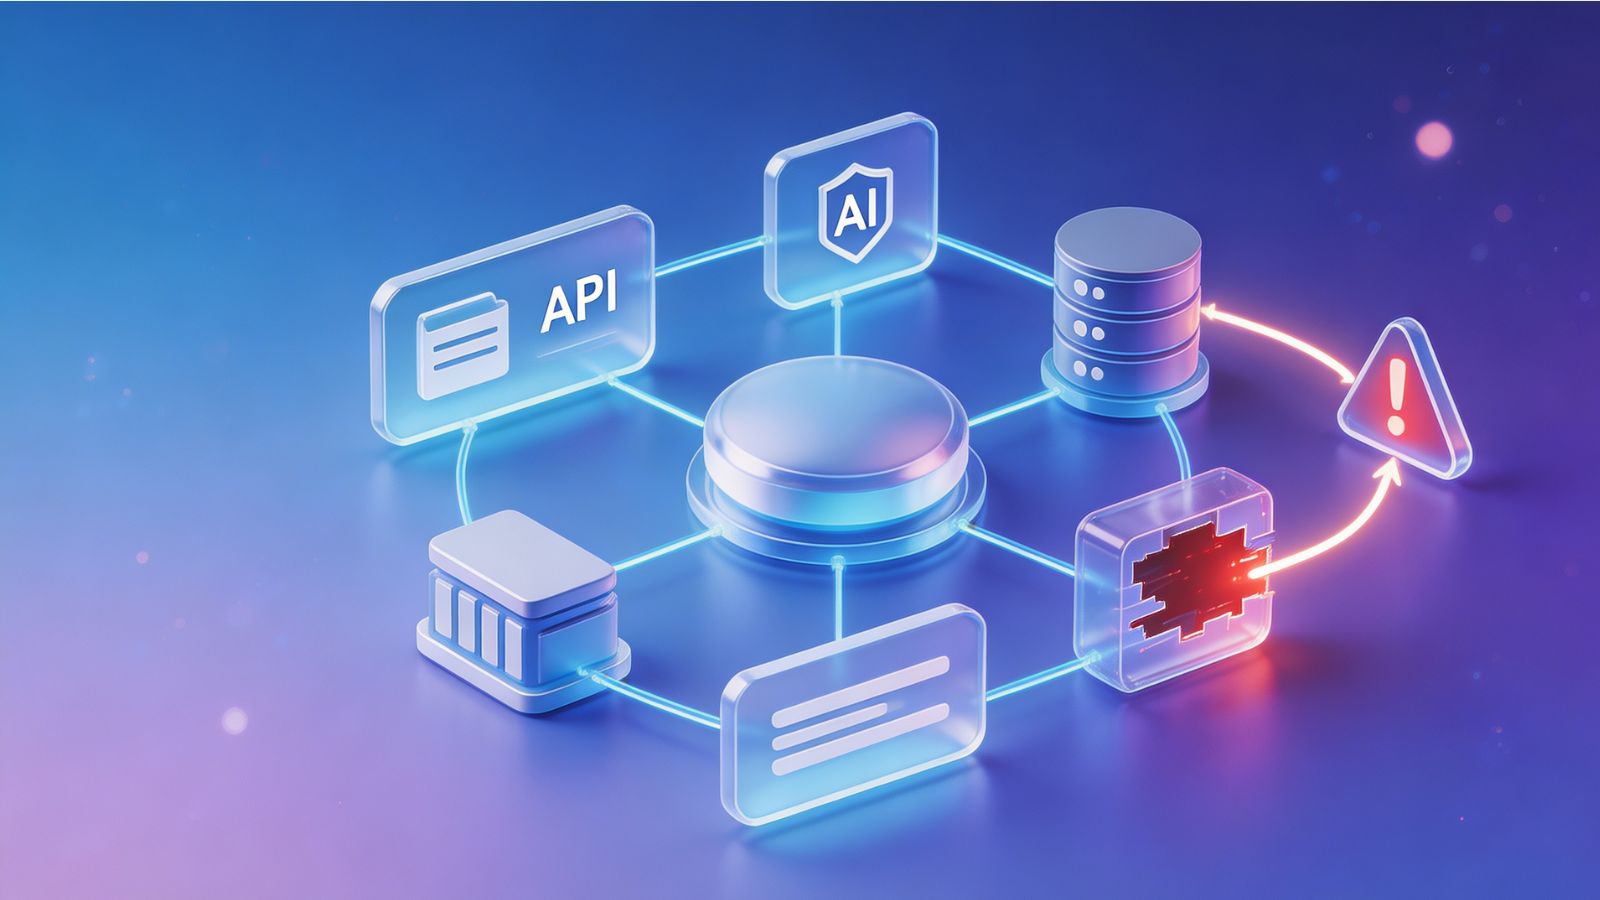
Reliability is broader than model accuracy.
NIST defines reliability as the ability of an item to perform as required, without failure, for a given period under specified conditions. For AI, this means considering the overall system and its operation over time.
An AI application can therefore have a highly capable model and still be unreliable.
Imagine a system that normally retrieves company documents before answering questions. If the retrieval service occasionally fails, the model may still generate an answer, but without the information it was supposed to use. From the user's perspective, the application has failed even though the underlying model itself is functioning.
Other components can create similar problems: authentication failures, unavailable APIs, incomplete data, software changes, overloaded infrastructure, or incorrectly configured prompts.
For this reason, evaluation should cover the entire AI system, not just the model in isolation.
A one-time evaluation provides only a snapshot.
AI systems operate in changing environments. Models can be updated, knowledge bases can change, prompts can be modified, and user behavior can shift. NIST's evaluation work emphasizes measurement and ongoing assessment as important parts of trustworthy AI development.
A practical monitoring process can maintain a set of representative evaluation cases and run them whenever a significant system component changes.
Organizations can also track production signals such as user corrections, escalation rates, failed requests, citation problems, and other application-specific indicators. These signals do not replace controlled testing, but they can reveal failures that were missed during development.
For high-impact applications, automated monitoring should be supplemented with appropriate human review. NIST's AI Risk Management Framework emphasizes that trustworthy AI involves human judgment, particularly when determining appropriate metrics and thresholds for a specific context.
A single percentage can make AI evaluation look simpler than it really is.
Suppose an application achieves a 95% overall accuracy rate. That number may sound reassuring, but it does not explain the remaining 5%.
If those failures are harmless formatting mistakes, the result may be acceptable. If they involve fabricated information in a high-impact workflow, the same number could be unacceptable.
NIST has also highlighted limitations in benchmark-style evaluations, including assumptions that can make results difficult to interpret and uncertainty that may not be properly quantified.
A stronger evaluation therefore reports performance by failure type, use case, and severity, rather than relying entirely on an aggregate score.
This gives developers something they can actually improve.
A useful evaluation set should not consist exclusively of questions that developers expect the system to answer correctly.
Include ordinary requests, difficult cases, edge cases, known failure modes, and examples representing the range of real users. Keep a portion of the evaluation data separate from material used to develop the system so that improvements are not judged only against examples the team has already seen.
For generative systems, reviewers should also distinguish between factual correctness, completeness, relevance, instruction-following, and style. A response can succeed on one dimension and fail on another.
NIST's generative AI evaluation program reflects this broader approach by examining capabilities and limitations across different tasks and modalities rather than reducing generative AI performance to a single measure.
Evaluating AI accuracy, consistency, and reliability is ultimately an engineering and measurement problem, not a matter of judging whether an answer “sounds right.”
Accuracy asks whether the result is correct. Consistency asks whether comparable situations produce appropriately stable behavior. Reliability asks whether the complete system continues to work as intended under its expected conditions.
The most useful evaluations connect all three to a specific application. They use representative test data, deliberately examine failure cases, establish measurable thresholds, and continue monitoring after deployment.
That approach also changes how teams improve AI systems. Instead of asking whether a model is simply “good” or “bad,” developers can identify where the system fails, how serious those failures are, and which part of the system needs attention.
For organizations deploying AI in real workflows, that is a far more useful question—and a much stronger foundation for deciding whether a system is ready for practical use.